Abstract
There is widespread recognition of the opportunity that AI offers to many organisations, and the inevitability that adaptation must take place. However, capturing this opportunity presents a step into the unknown. Principled methodologies are needed to decide what should remain as human discernment, what to automate, and how to manage the uncertainty of a rapidly changing technology that is uncertain by nature.
Function Analysis is a long established methodology that considers what products and process ‘do’ not what they ‘are’. The obvious connection to AI is that agents ‘do’ things; performing functions on behalf of the designer. With a better understanding of what we want agents and machines to do, we can express our instructions in terms of outcomes that are valuable to us. There is also a long history of frameworks and methodologies for managing risk and uncertainty in complex safety critical systems. The success of these frameworks is evidenced by the increase in safety over decades.
This paper introduces pFAST (probabilistic Function Analysis System Technique), an extension of established function analysis, adapted for the age of AI. pFAST provides a structured method for decomposing processes into their constituent functions, assessing the risk profile of each function using the CARBS framework (Criticality, Assessability, Rectification, Base rate, Stability), and making principled decisions about human versus machine execution. The approach is intended to help organisations design AI-augmented processes that are explicitly risk-assessed, auditable, less tightly coupled to today’s tools, and cost-effective.
Base rate, the prior probability that a given function produces a correct output, is a quantitative dimension not found as an explicit input in the published AI risk frameworks surveyed for this paper. It assesses the anticipated reliability or success rate of the function at the time of design. Its inclusion directly addresses the well-documented cognitive trap of base rate neglect, identified in ‘Thinking, Fast and Slow’ as a primary driver of overconfident assessments.
Evidence status
This paper proposes and illustrates pFAST. pFAST has not yet been empirically validated.
The components of the approach (function analysis, reliability engineering, failure-mode analysis, human oversight and probabilistic reasoning) are established disciplines. The contribution proposed here is their synthesis and application to the design or evaluation of AI-enabled business processes.
The worked example is a proof of concept. It shows how the method can be applied to a single AI function and how the resulting assessment informed a design decision. The reliability figures in the example (65 to 75% unassisted, 97 to 98% with diverse redundancy) are design-stage estimates generated by an LLM during development. They are included to show how reliability can be reasoned about at design stage, not as results. Operational data gathered since launch is reported in the worked example, including what it does and does not confirm.
The central hypothesis is that explicit functional decomposition, combined with structured assessment of criticality, assessability, rectification, base rate and stability, improves the design, assurance and ongoing management of AI-enabled processes. Testing that hypothesis across complete workflows and against observed data is the next stage of the work.
What is Function Analysis?
Function analysis is the discipline of identifying and describing what an object or process does functionally. Its purpose is to strip away assumptions about what something is and consider what it does so that alternative, potentially better and more efficient solutions can be identified.
Function Analysis has its origins in General Electric’s procurement function during the Second World War. Shortages led to suppliers being asked to offer alternatives that could function in the same way as rubber, steel and other materials that were unavailable. Function Analysis was codified in the 1960’s by Charles Bytheway. Since then function analysis has been an underlying discipline for value engineering and value management. Note that the term “value engineering” has acquired a separate meaning in the AI field, referring to the alignment of AI systems with human values and ethics. Function analysis is also an underlying discipline of TRIZ, a method for inventive problem solving that draws on established patterns.
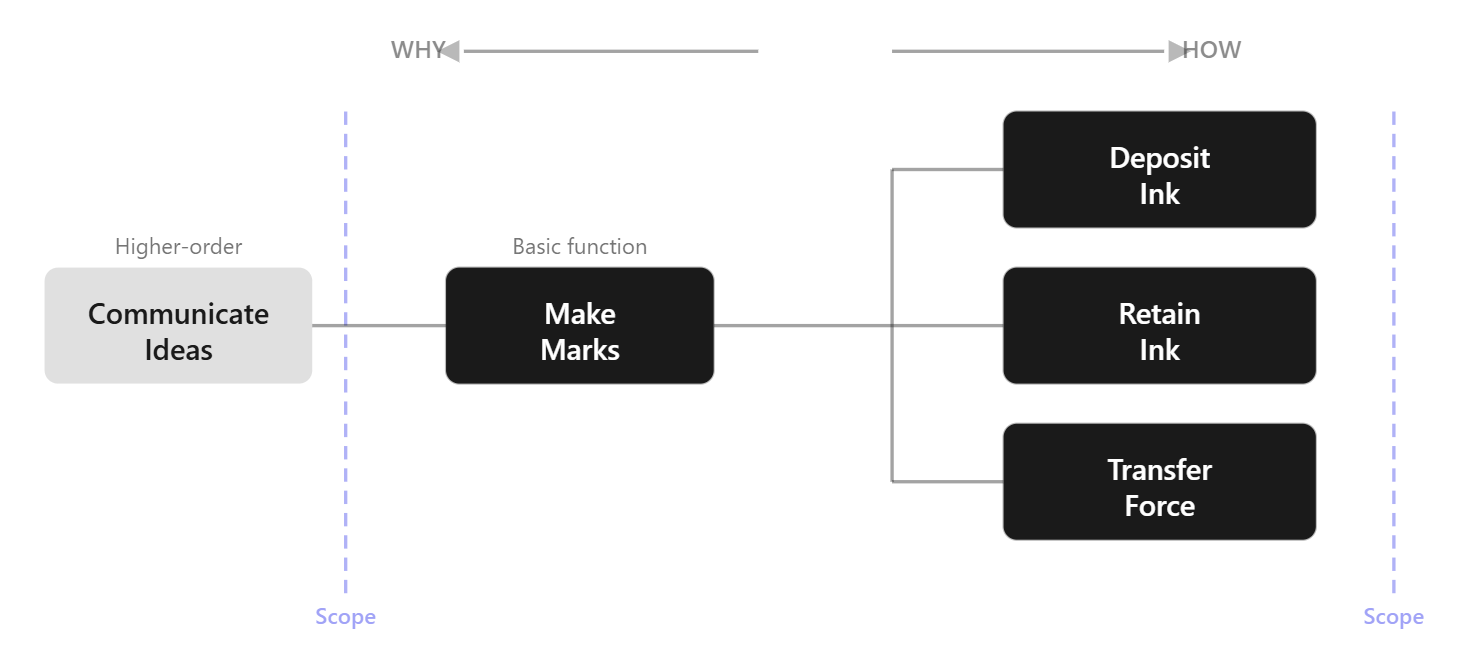
Central concepts in function analysis are function definition and How/Why logic. Individual Functions are codified as verb-noun pairs. For instance, the basic function of a road bridge is ’Span Gap’. It has other functions like ‘Look Good’ (an aesthetic function) and ‘Separate Traffic’ (safety function). The functionality of a process, product or object can be expressed by listing its functions and sub functions using verb-noun pairs.
The way in which functions work together as a system can be shown graphically in a FAST (Function Analysis System Technique) diagram. This displays the hierarchy of functions in a tree structure. The hierarchy is derived from ‘How/Why’ Logic. Working from left to right the logic is ‘how’ is this function performed? Then from right to left ‘Why’ is this function performed.
Although it can be explained simply, function analysis can be a challenging and intellectually intensive exercise. This is because it creates deep reflection on the product or process being analysed. Many processes and products incorporate deeply embedded assumptions and perspectives that are no longer relevant.
Probability and Uncertainty
Historically, the subjects of function analysis were, or would often be treated as, deterministic and objective systems, whether physical devices or software code. In practice, there were often process functions performed by people that were both subjective and probabilistic: for instance, “Summarise Change-Request” might produce different outputs from different people given the same input. However, this uncertainty was often accepted rather than explicitly managed.
Functions fulfilled by AI are probabilistic in nature: the system may not perform with 100% accuracy, and it may produce different responses to the same input on different occasions. They are not only probabilistic in the moment, but they are also subject to change over time. Models evolve and adapt, and human behaviour is changing in response to the introduction of new technology.
The introduction of AI has brought probabilistic characteristics into sharp focus as a design consideration. When a function is performed by a large language model, the designer must account for variability, hallucination, context-sensitivity and the absence of guaranteed outcomes. This is, in essence, a risk and uncertainty management challenge.
Lusser’s Law: “Weaker than the weakest link”
In order to achieve overall system reliability, reliability of individual functions needs to be higher than intuitively might be expected. This principle has been understood since the 1950s, when German engineer Robert Lusser formalised it as Lusser’s Law during rocket component reliability analysis. Recent academic work has confirmed its applicability to AI systems; error compounding across multi-step and multi-agent workflows may be one of the central reliability challenges of the AI era. The table below shows the effect of this reliability/error compounding.
| Individual function reliability | 2 nodes | 5 nodes | 10 nodes | 20 nodes |
|---|---|---|---|---|
| 99.9% | 99.8% | 99.5% | 99.0% | 98.0% |
| 99% | 98.0% | 95.1% | 90.4% | 81.8% |
| 95% | 90.3% | 77.4% | 59.9% | 35.8% |
| 90% | 81.0% | 59.0% | 34.9% | 12.2% |
| 80% | 64.0% | 32.8% | 10.7% | 1.2% |
| 70% | 49.0% | 16.8% | 2.8% | 0.1% |
For instance, a process with five individual functions, each of which is 95% reliable, results in only a 77% reliability of the process overall. This assumes that the individual functions are independent, it may also be the case that errors compound in a non-linear manner making matters worse. This is straightforward compound probability: 0.95⁵ = 0.774.
Probabilistic Function Analysis System Technique
pFAST (probabilistic Function Analysis System Technique) extends the classic FAST by explicitly incorporating uncertainty assessment into the functional decomposition. Each function in the tree is not only defined and positioned in the How/Why hierarchy, but also assessed for its risk profile if it is executed by a probabilistic agent.
For a simple sequential workflow in which every function must succeed, and assuming the functions fail independently, overall reliability is the product of the individual node reliabilities. pFAST uses this as a baseline for reasoning at design stage, not as a general reliability model. Real workflows contain conditional branches, retries, human intervention, fallback paths and correlated errors (Annexe A identifies correlated errors as a residual failure mode in the worked example), and these can make the true figure better or worse than the simple product. The baseline is still useful: it sets a reliability budget for each node that the design must meet, and once deployed the system can be monitored to see whether that budget is being met. Where it is not, the node-level figures become diagnostics that point to where the design needs attention.
The risk framework for assessing the nodes is called CARBS.
The CARBS Risk Assessment Framework
Once functionality is understood, each automated function in the pFAST tree is assessed against five dimensions, grouped as CARBS: Criticality, Assessability, Rectification, Base Rate, and Stability. The first four (CARB) assess the function at a point in time; the fifth (S) is reflective and asks how long that assessment will remain valid. Together, these determine whether an individual function should be assigned to human discernment, an AI agent, a deterministic script, or some other solution.
CARBS does not claim radical conceptual novelty: it is a selection and reframing of established reliability & risk frameworks. Mostly, these frameworks have been used in applications where very high reliability is required, for instance, avionics and railway signalling. The general business and administration context is different; a lower level of reliability is acceptable. If a totally manual process was replaced with an automated process that was only 50% reliable but always ‘failed safe’ and reverted to a manual process, this could still be valuable from a productivity perspective. CARBS is calibrated for this reality: it asks not “can this be made perfect?” but “what level of reliability is needed here, and how will we know when we fall short?”
AI presents unique challenges compared to the deterministic systems for which classical reliability engineering was developed: adaptability, inscrutability, and emergent behaviours mean that AI cannot be treated as a complex but predictable component. The closest structural analogue is FMEA (Failure Mode and Effects Analysis), which similarly uses Severity, Detectability, and Occurrence dimensions. However, CARBS differs in three important ways: it operates at the AI function level rather than the mechanical failure mode level; it introduces Base Rate as a discrete prior-probability dimension (reframed from FMEA’s failure-focused Occurrence into a positive, function-level prior); and it adds Stability as a time dependent meta-dimension.
| Dimension | Description | Notes & lineage |
|---|---|---|
| Criticality | How important is it that this function is performed correctly? Does the function ‘fail safe’, ‘fail dangerous’ or is it ‘intrinsically safe’. | Appears in Failure Mode and Effects Analysis (FMEA) & Failure Mode Effects and Criticality Analysis (FMECA). HAZOPs. |
| Assessability | Can it be determined, quickly (before follow-on action) and cheaply, whether the function was performed correctly? | Analogous to audit and control effectiveness assessments (e.g. ISO 9001). |
| Rectification | How easily and at what cost can a mistake be corrected? Or a situation recovered? | Maps closely to FMEA’s “Detectability” and “Severity” dimensions. |
| Base Rate | With what frequency can the function be expected to perform correctly? Which solution offers the highest reliability? | Directly borrowed from statistics and Bayesian reasoning. Base rate neglect, the tendency to ignore prior probabilities when making judgements, is cited in Kahneman’s Thinking, Fast and Slow as a primary driver of overconfident assessments. |
| Stability | How long will the CARB assessment of this function remain valid? A meta-dimension sitting above the other four, assessed at both function level (is this function’s risk profile liable to change?) and system level (does the process remain stable as AI and human behaviour co-evolve?). The practical output is a reassessment trigger: a recommended frequency or event at which the CARB analysis should be re-run. | No direct equivalent. Unlike CARB dimensions (which assess static properties), Stability addresses temporal validity: the recognition that AI systems drift, update, and alter the human behaviour around them. High Stability = long reassessment interval. Low Stability = frequent re-evaluation required. Instrumentation (token cost, agreement rate, override frequency) provides empirical early warning of degrading Stability. |
CARBS is currently a structured assessment framework rather than a calibrated quantitative model. It gives the designer five questions to answer explicitly and a vocabulary for recording the answers. Scoring scales, weightings, decision thresholds, the method for turning a Stability judgement into a reassessment interval, and evidence that different practitioners would reach similar assessments are all areas for development, and are set out in the Limitations section.
Intended Benefits of pFAST for Technology Transformation
The central challenge with the implementation of AI is how to capture the opportunity it presents whilst also managing the risks. These risks take a number of forms, failed implementation risk, cost risk, either in development or during its operation. The anticipated benefits of using Function Analysis and quantitative risk assessment in the AI technology transformation:
Clarity of Purpose – The higher-order function crystallised during the FAST analysis is what the user or organisation actually wants the process or product to do. The discipline of Function Analysis pushes the designer to decompose functions thoughtfully in pursuit of the higher order function. This means better expression of the designer’s intent and fewer gaps for the AI to fill in, which the AI will often do through generic patterns recognised in the training data.
Appropriate Division of Labour and Solutions – Each function node on the FAST tree can be considered for: human discernment, expert judgement, agent-with-tool, sub-agent or deterministic script. This provides a principled alternative to the current ad-hoc “string some prompts together” approach. Potentially, the functional blueprint provides evidence and traceability that the process was ‘designed to function right’ in regulatory contexts or where design decisions need to be reviewed by others.
Increased likelihood of success – the hypothesis is that explicit, quantitative management of risk and uncertainty from a functional perspective increases the likelihood that a solution will do what is intended. This is the core claim of pFAST and the one that most needs testing. Fundamentally, this is a risk based approach: assigning executors based on an appreciation of reliability and uncertainty.
Reduced coupling to today’s tools – If the specification is functional (“validate invoice”, “schedule site-visit”, “summarise risk-register”), the specification outlives the implementation. This looks like one of the biggest practical problems in AI adoption: organisations write agent requirements in terms of today’s tools, and the specifications are out of date within weeks or months. A functional specification is not immune to change (the Stability dimension exists precisely because the risk profile of a function moves even when its definition does not), but it does give a stable point of reference from which to review and update the implementation.
Value engineering and LEAN Operations for AI deployment – Classic value engineering sought the cost-to-perform each basic function compared to the benefit it brings. In the modern agent context, we now have hard numbers: tokens, API calls, latency, error rate per function.
FAST Brainstorming Application: A Live Proof of Concept
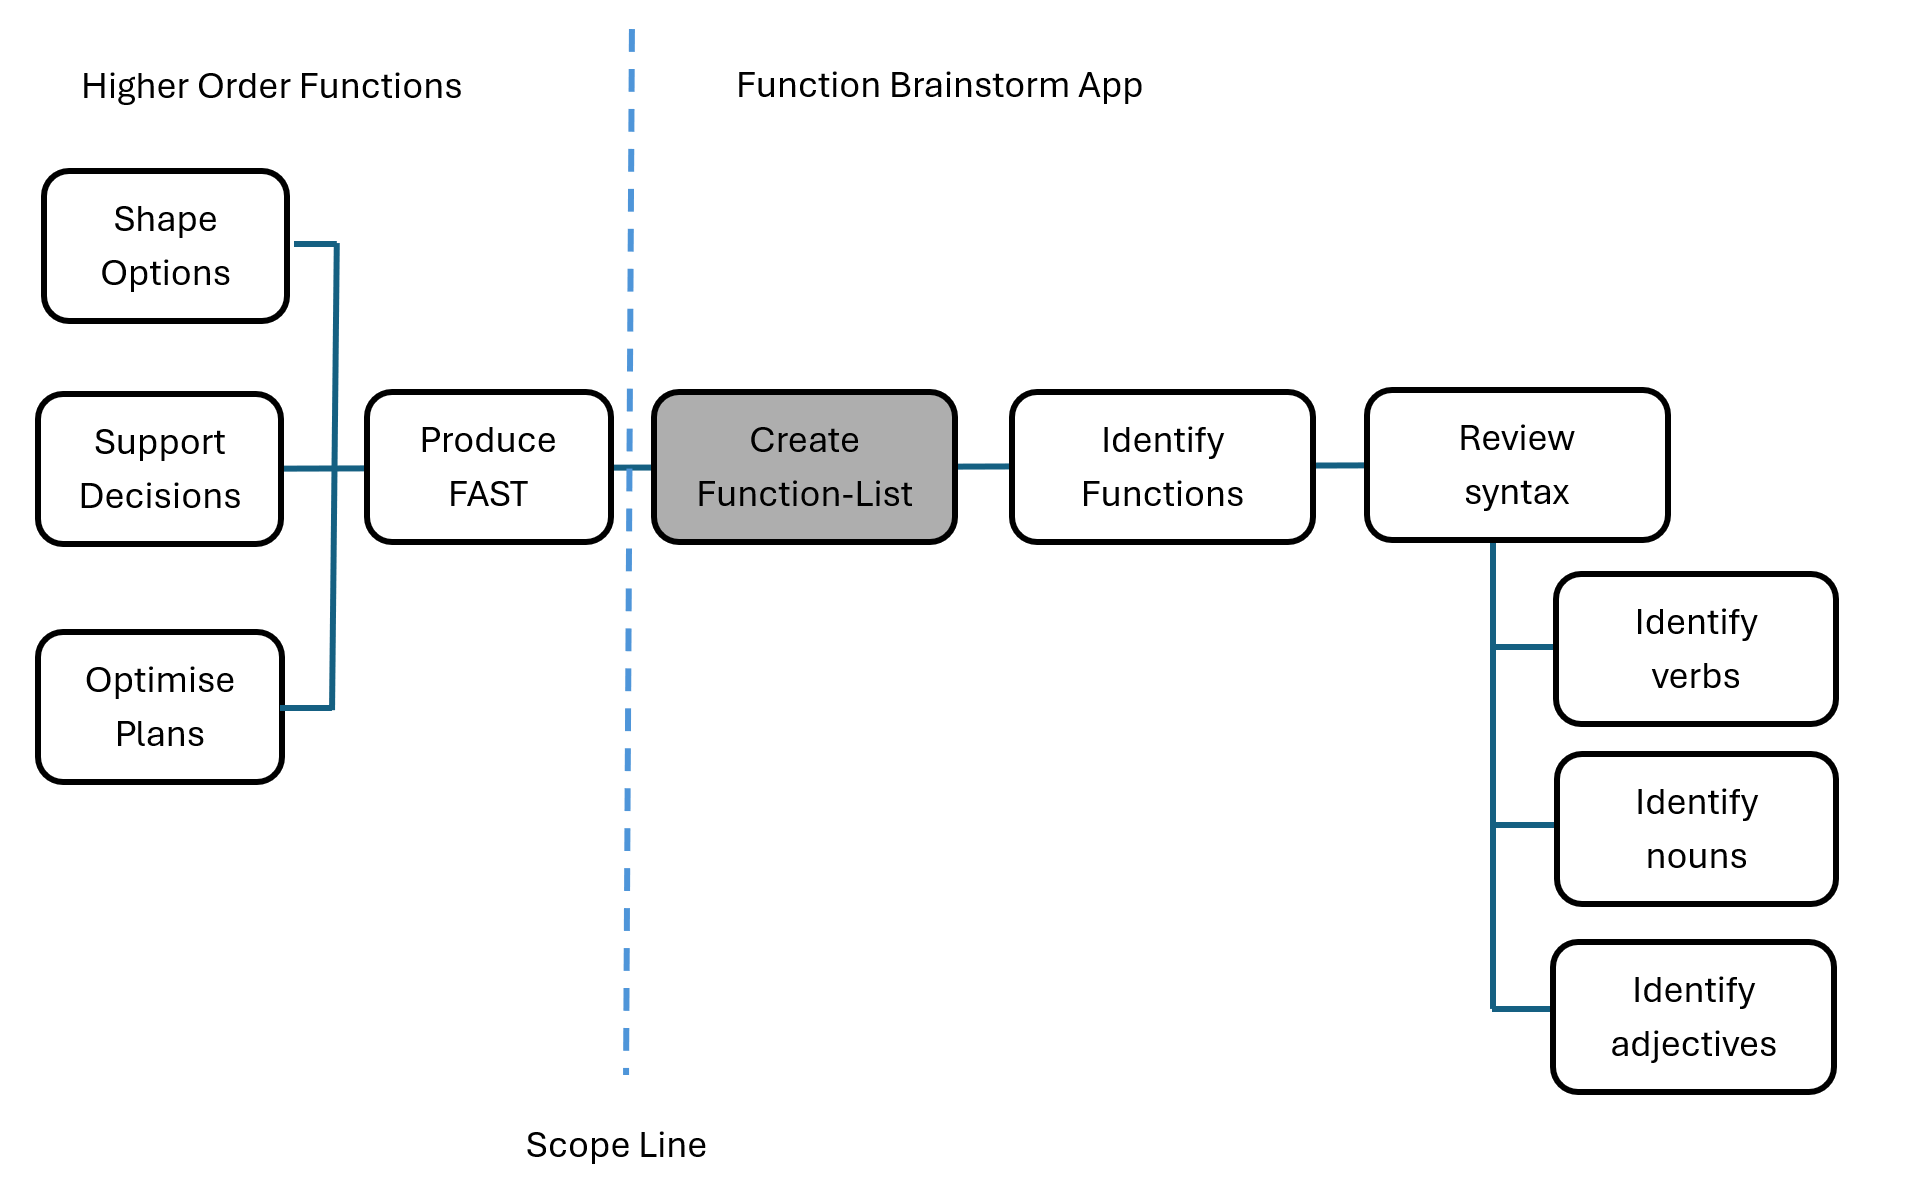
To demonstrate pFAST in practice, consider the creation of a Function Analysis Brainstorm App, a tool that coaches users through the first stage of creating a FAST diagram: brainstorming and validating functions. The application is live at functionanalysis.app. The app reviews brainstormed items, filters out items that are not functions, and suggests modifications to achieve the verb-noun pair format. The process can be summarised as follows: the basic function of the brainstorm stage is ‘create function-list’.
Applying the CARB framework to the core function “Review Function-Syntax”:
| Dimension | Assessment |
|---|---|
| Criticality | Medium. Incorrect syntax review leads to poorly formed functions in the FAST diagram, but the consequences are confined to the quality of the brainstorm: no safety, financial or legal impact. As a coaching app, all syntax is reviewed by humans anyway. |
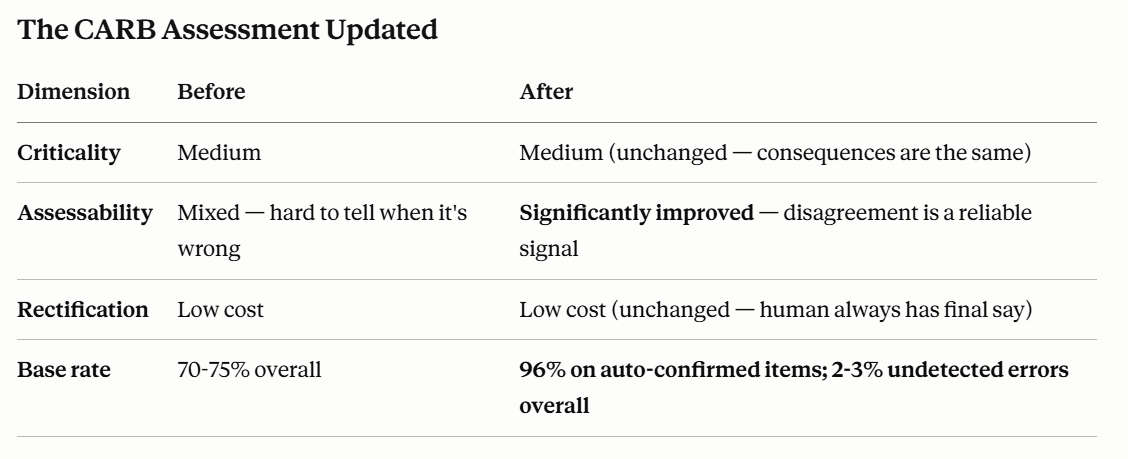
| Assessability | Mixed. Verb form and hyphenation can be checked programmatically. However, determining whether a noun is “too vague” or whether an item is a function versus a design objective requires human judgement. The AI can flag potential issues but cannot definitively resolve ambiguous cases. |
| Rectification | Low cost. The user can override any classification, edit any function text, and move items between categories at any point. The coaching model means no AI decision is final; the human always has the last word. |
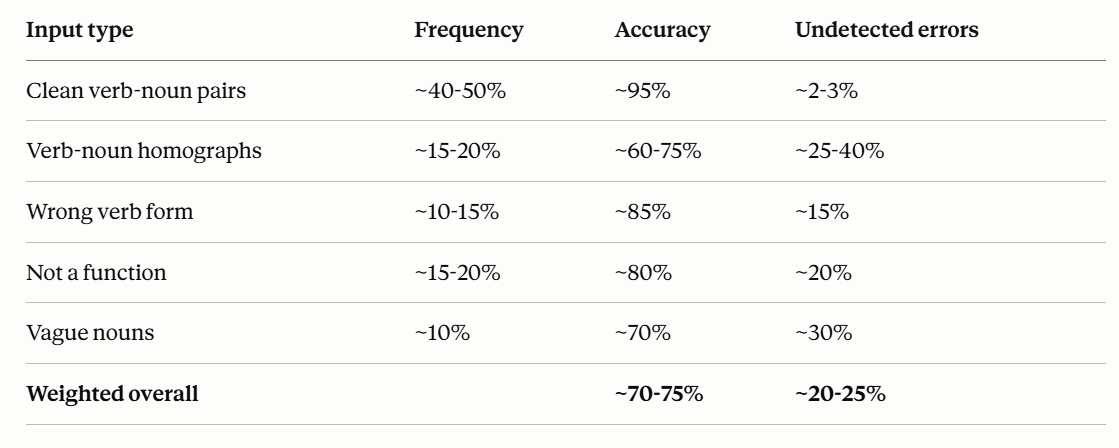
| Base Rate | Design-stage estimate: 65 to 75% unassisted accuracy (LLM-generated; see below). Clean verb-noun pairs were estimated to be classified correctly around 95% of the time, with verb-noun homographs (words like “fire”, “support”, “process”, “measure” and “invoice” that can be either verb or noun) dropping the estimate to 57 to 75%. |
| Stability | Assessed as high at design stage: the models were fixed in the workflow and the use case was stable. This assessment has already proved optimistic; see the note on Stability below. |
Claude was prompted to estimate the reliability of the process as initially designed. The estimate was a relatively low base rate of success, 65 to 75%. Because the process was designed as a coaching app there would always be a human in the loop, so the risk was low; but a low reliability would be irritating and inefficient.
Many will question whether an LLM should be asked to assess its own reliability, and whether it will be as optimistic about its abilities as a human tends to be. That doubt is well founded, and it is worth being explicit about what the figures in this section are: forecasts produced by the system under assessment, not measurements. The irony is useful rather than embarrassing. pFAST asks for an explicit prior on every probabilistic function, and the example shows how weak that prior can be when the only available source is the model itself. Base rates anticipated at design should be treated as priors, to be tested and updated during commissioning and operation, whether the estimate came from a human or from an AI.
From risk assessment to design intervention
The CARB assessment led to a specific design decision. The initial assessment identified imperfect reliability and limited assessability as the risks. Rather than relying on a single AI model, the app therefore uses diverse redundancy: two models with deliberately different prompts (one a strict grammarian, the other a FAST methodology coach) analyse each input in parallel. When they disagree, the item is flagged for human review with both interpretations presented. This is directly analogous to dissimilar redundancy in avionics and railway signalling, where independent systems with different designs and development teams protect against common-mode failure. The point of the intervention is not that it was known to perform better; it is that it converts some potentially silent errors into observable disagreements, which is the mechanism by which Assessability is improved.
A further Claude prompt estimated that this architecture would raise reliability to 97 to 98% (Annexe A), reducing undetected errors from roughly 20 to 25% to 2 to 3%, at the cost of flagging around 45% of inputs for human review. These are design hypotheses, not observed performance. What the exercise does demonstrate is that a CARB assessment can produce a concrete, falsifiable engineering decision: the predicted flag rate, the predicted undetected error rate and the predicted targeting of human effort on ambiguous cases can each be checked against operational data.
The workflow was instrumented to capture tokens consumed per function, latency, monetary cost, routing decision (auto-confirmed, soft-flagged or hard-flagged) and human override. The full technical details of the prompt design and the diverse redundancy workflow are in Annexe B.
What the operational data shows so far
Between 10-Jun-2026 and 09-Sep-2026 the log recorded 417 inputs over 14 days of use. Of these, 233 (56%) were auto-confirmed, 27 (6%) soft-flagged and 157 (38%) hard-flagged, so 44% of inputs were routed to human review. Mean consumption was 1,706 tokens and £0.0027 per input; the whole run cost £1.13.
The flag rate is strikingly close to the 45% forecast at design stage by the LLM. That is a narrow but real piece of predictive validity: the forecast of how much human attention the architecture would demand was accurate. It says nothing, however, about whether the auto-confirmed items were correct, which is the claim that matters.
The reason is an instrumentation gap. The log has columns for human override, human agreement and final classification, and none of them was ever populated: the application records the models’ decision but does not capture what the human did with it. In pFAST terms, Assessability was designed into the architecture (disagreement makes uncertainty visible) but the feedback loop that would turn visibility into measured reliability was never closed. So the 2 to 3% undetected error estimate remains untested. Two further caveats apply: session identity was not recorded, and a large share of the inputs are likely to be the author’s own testing rather than independent users, so the sample is neither large nor representative.
This is exactly the kind of gap pFAST is meant to surface, and it is reported here because a methodology for managing uncertainty is not credible if its own proof of concept hides the uncertainty. Closing the loop, by capturing the human’s final decision for every flagged and unflagged item, is the first item of further work.
A note on Stability
The design-stage assessment rated Stability as high because the models were fixed and the use case stable. Within four months that assessment is already being overtaken, for two reasons. First, operational experience has prompted a redesign of the syntax-review function to handle words that can be both verbs and nouns. For instance, “invoice” is a verb in “invoice customer” and a noun in “issue invoice”. These were more prevalent than anticipated, possibly because humans resolve them subconsciously and so do not notice them as a difficulty. This means that the prompts, and possibly the models, will change. Second, a new class of executor has appeared: TypeSafe AI’s Jev, a model built to return typed classification decisions with calibrated confidence rather than free text. If a classifier of that kind can review function syntax with a known confidence, the Base Rate, Assessability and cost of the node could all change, and the case for running two general-purpose LLMs in parallel would need to be re-made. (At the time of writing the author is on the waiting list for access and has not tested it.)
Neither change invalidates the functional specification; “Review Function-Syntax” remains the function. Both change the CARB profile of the node. Stability was lower than assessed, and the assessment should have carried an explicit reassessment trigger, such as “re-run on any change to prompts or models, or on the availability of a specialised classifier”. That is the lesson of the dimension, demonstrated on the author’s own design.
Conclusion
The rush to implement AI in business processes is understandable, but speed without design discipline imports the risk of fragile, opaque, and wasteful systems. pFAST offers an alternative based on established and proven function and risk management methodologies: decompose the process into its functions, assess each function’s risk profile with CARBS, and make principled decisions about who or what should execute each function.
The Stability dimension ensures that this is not a one-time exercise: CARBS builds in a reassessment trigger, recognising that AI systems drift and that the humans working alongside them adapt. A CARBS assessment conducted today has a time limited validity; the framework asks practitioners to specify the conditions under which they will re-run it. The appearance of Jev within months of the first edition suggests that, for the coming phase of AI development, Stability driven by technology change is likely to be low: the set of available executors is changing faster than the processes they serve.
The approach has been applied to a live system, and the worked example shows what pFAST produces: an explicit CARB assessment, a design decision traceable to it, falsifiable predictions, and instrumentation that can test them. It also shows what the proof of concept has not yet produced: measured reliability. It is a step from “we think this AI workflow is good enough” towards “here is the evidence that this process was designed to function correctly, and here is how we are checking that it does”, but only a step.
It is important to be candid about what the brainstorm app demonstrates and what it does not. It is a proof of concept for a single function node, not a system-level validation of pFAST across a complete multi-function workflow. The brainstorm app will continue to serve as a test bed. Once the human-feedback loop is closed, monitoring reliability for classes of functions over time will allow the Stability dimension to be assessed empirically, detecting when model updates, prompt changes or data drift alter the reliability profile before the change is felt operationally.
Demonstrating that this approach delivers predicted reliability and functional gains across an entire process workflow, measuring at each node and at system level, is the next evidential step. The instrumentation is largely in place; what is needed is the feedback loop described above and application to more complex workflows.
Limitations
This paper has several important limitations. They are stated here so that the reader can weigh the claims accordingly.
Limited empirical evidence. The worked example concerns a single function within a function-brainstorming application. It is not evidence of system-level reliability or of the general effectiveness of pFAST.
Design-stage reliability estimates. The reliability figures in the example were generated by an LLM during design. They are hypotheses to be tested against observed data, not measured performance.
Untested accuracy. The operational log confirms the predicted volume of human review but not the predicted error rate, because the human’s final decision was never captured. The 2 to 3% undetected error estimate is unverified.
Unvalidated CARBS scoring. The paper proposes the CARBS dimensions but does not yet establish scoring scales, weightings, decision thresholds, consistency between practitioners or predictive validity.
Simplified reliability model. Multiplying node reliabilities assumes a series system with independent failures. Real AI workflows contain dependencies, branching, retries, human intervention and correlated errors.
Limited external validity. The transfer of reliability-engineering practice from safety-critical domains to business processes is argued by analogy, not demonstrated. The method has been applied in one domain, the author’s own.
No controlled comparison. pFAST-designed processes have not been compared with processes designed by other means.
Commercial context. pFAST was developed by Shape Select Optimise and the author offers pFAST assessments as a consultancy service. The example is the author’s own application. No independent evaluation has yet been undertaken.
These limitations define the next stage of the work rather than qualifying it away: closing the feedback loop, calibrating CARBS across practitioners, and applying the method to a complete multi-node workflow with observed outcomes.
Putting pFAST to Work
If you are considering how AI can be introduced into a business process, want clarity on what it should do, and are concerned about reliability and about specifications that go stale, a pragmatic way to begin is to start small: take a single process you are considering automating and put it through a pFAST decomposition and a CARBS assessment. The output is a functional blueprint that shows which functions to automate, which to keep under human discernment, what reliability to expect of each and, just as importantly, how you will know whether that expectation is being met.
There are two ways to begin. To try the method yourself, the function-brainstorm app described above is live at functionanalysis.app; it will coach you through decomposing and validating the functions of a process in a few minutes. For a worked review of one of your own processes, get in touch to arrange a scoped pFAST assessment.
Two ways to start
Try the method yourself, or have one of your own processes reviewed.
Open the Function Analysis App Arrange a pFAST assessmentAbout the Author
Stephen Cresswell works independently on problems that require both analysis and judgement. His background spans project risk management, value engineering and innovation, with over twenty years advising complex projects and organisations. He holds a degree in Physics and a postgraduate diploma in Strategy and Innovation from Oxford Saïd Business School. He practises function analysis, risk management and value management directly through his consultancy, Shape Select Optimise (www.ssovalue.co.uk).
Annexe A: Raw Claude Outputs for Estimation of Base Rate Reliability
Base Rate: Before vs After Diverse Redundancy.
Before (single model)
After (diverse redundancy)
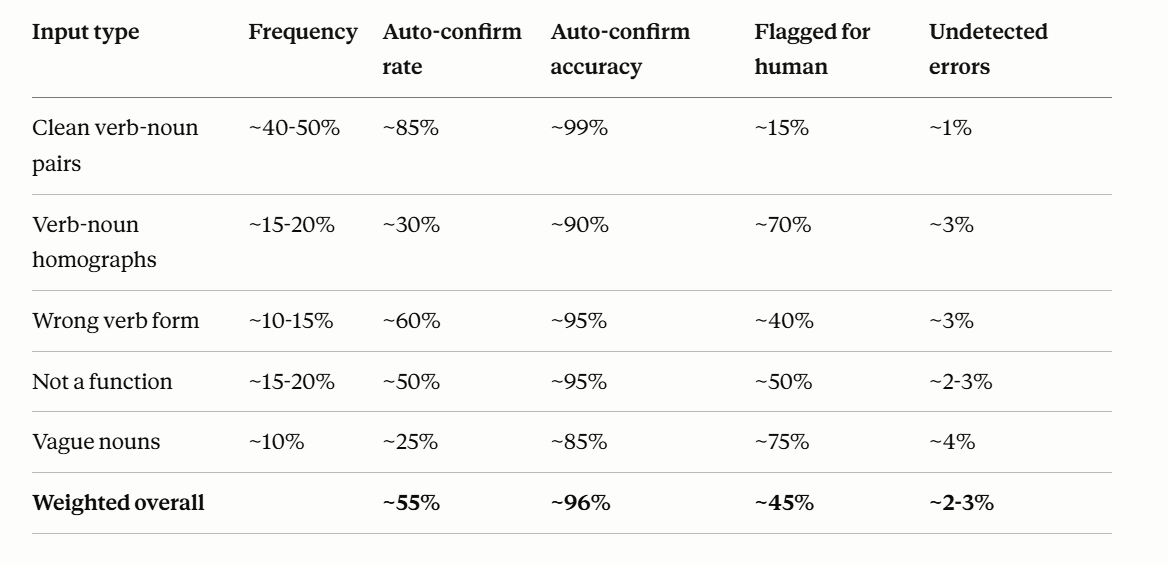
The system now has three outcomes per input: auto-confirmed (both agree), soft-flagged (partial agreement), hard-flagged (disagreement). Each has a different error profile. The key shifts:
Undetected error rate drops from ~20–25% to ~2–3%. This is the main win. The system doesn’t necessarily get more right — it gets better at knowing when it’s wrong. Disagreement between models is a reliable signal that human judgement is needed.
The cost is human review volume. ~45% of inputs get flagged, which sounds high, but those are precisely the inputs that would have been silently misclassified before. The human effort is now targeted at genuine ambiguity rather than spread across everything.
Failure Modes: What Changes
1. Verb-noun homographs (“fire”, “support”, “process”). Before: silent misclassification ~30% of the time. After: the grammarian flags the word as ambiguous while the FAST coach interprets it in context. Disagreement triggers review ~70% of the time. The “support structure” test actually showed agreement — both models correctly read “support” as the verb in that context. The system is better at handling these than expected.
2. Not-a-function inputs (“fast turnaround”). Before: ~20% slipped through as false positives. After: the live test showed this working perfectly — both models identified no verb and disagreed on the noun, producing a soft-flag with the coaching note “performance attribute.” This category is largely solved.
3. Vague nouns (“Provide service”, “Manage things”). This remains the hardest category. Both models may agree that it’s a valid verb-noun pair (it is, syntactically) but disagree on whether the noun is “specific enough.” The FAST coach prompt is designed to catch this, but “vague” is inherently subjective. Base rate improvement is modest — from ~70% to ~85% on auto-confirmed items.
4. New failure mode: correlated errors. If both models share the same blind spot (e.g. both trained on similar data that treats “ensure compliance” as a valid function), they’ll agree confidently on a wrong answer. This is the ~2–3% residual. The diverse prompts mitigate this (a grammarian sees “ensure” differently from a FAST coach), but can’t eliminate it entirely.
5. New failure mode: false flags. The system may flag items that are actually fine — both models get it right but express the answer slightly differently (e.g. “development-costs” vs “development costs” as the identified noun). This wastes human review time without improving quality. The comparison logic’s tolerance for minor differences matters here.
The biggest CARB improvement is Assessability. The system has moved from “you can’t easily tell when it’s wrong” to “it tells you when it’s uncertain.” That’s the value of diverse redundancy — it converts silent failures into visible flags.
Annexe B: Agent Implementation
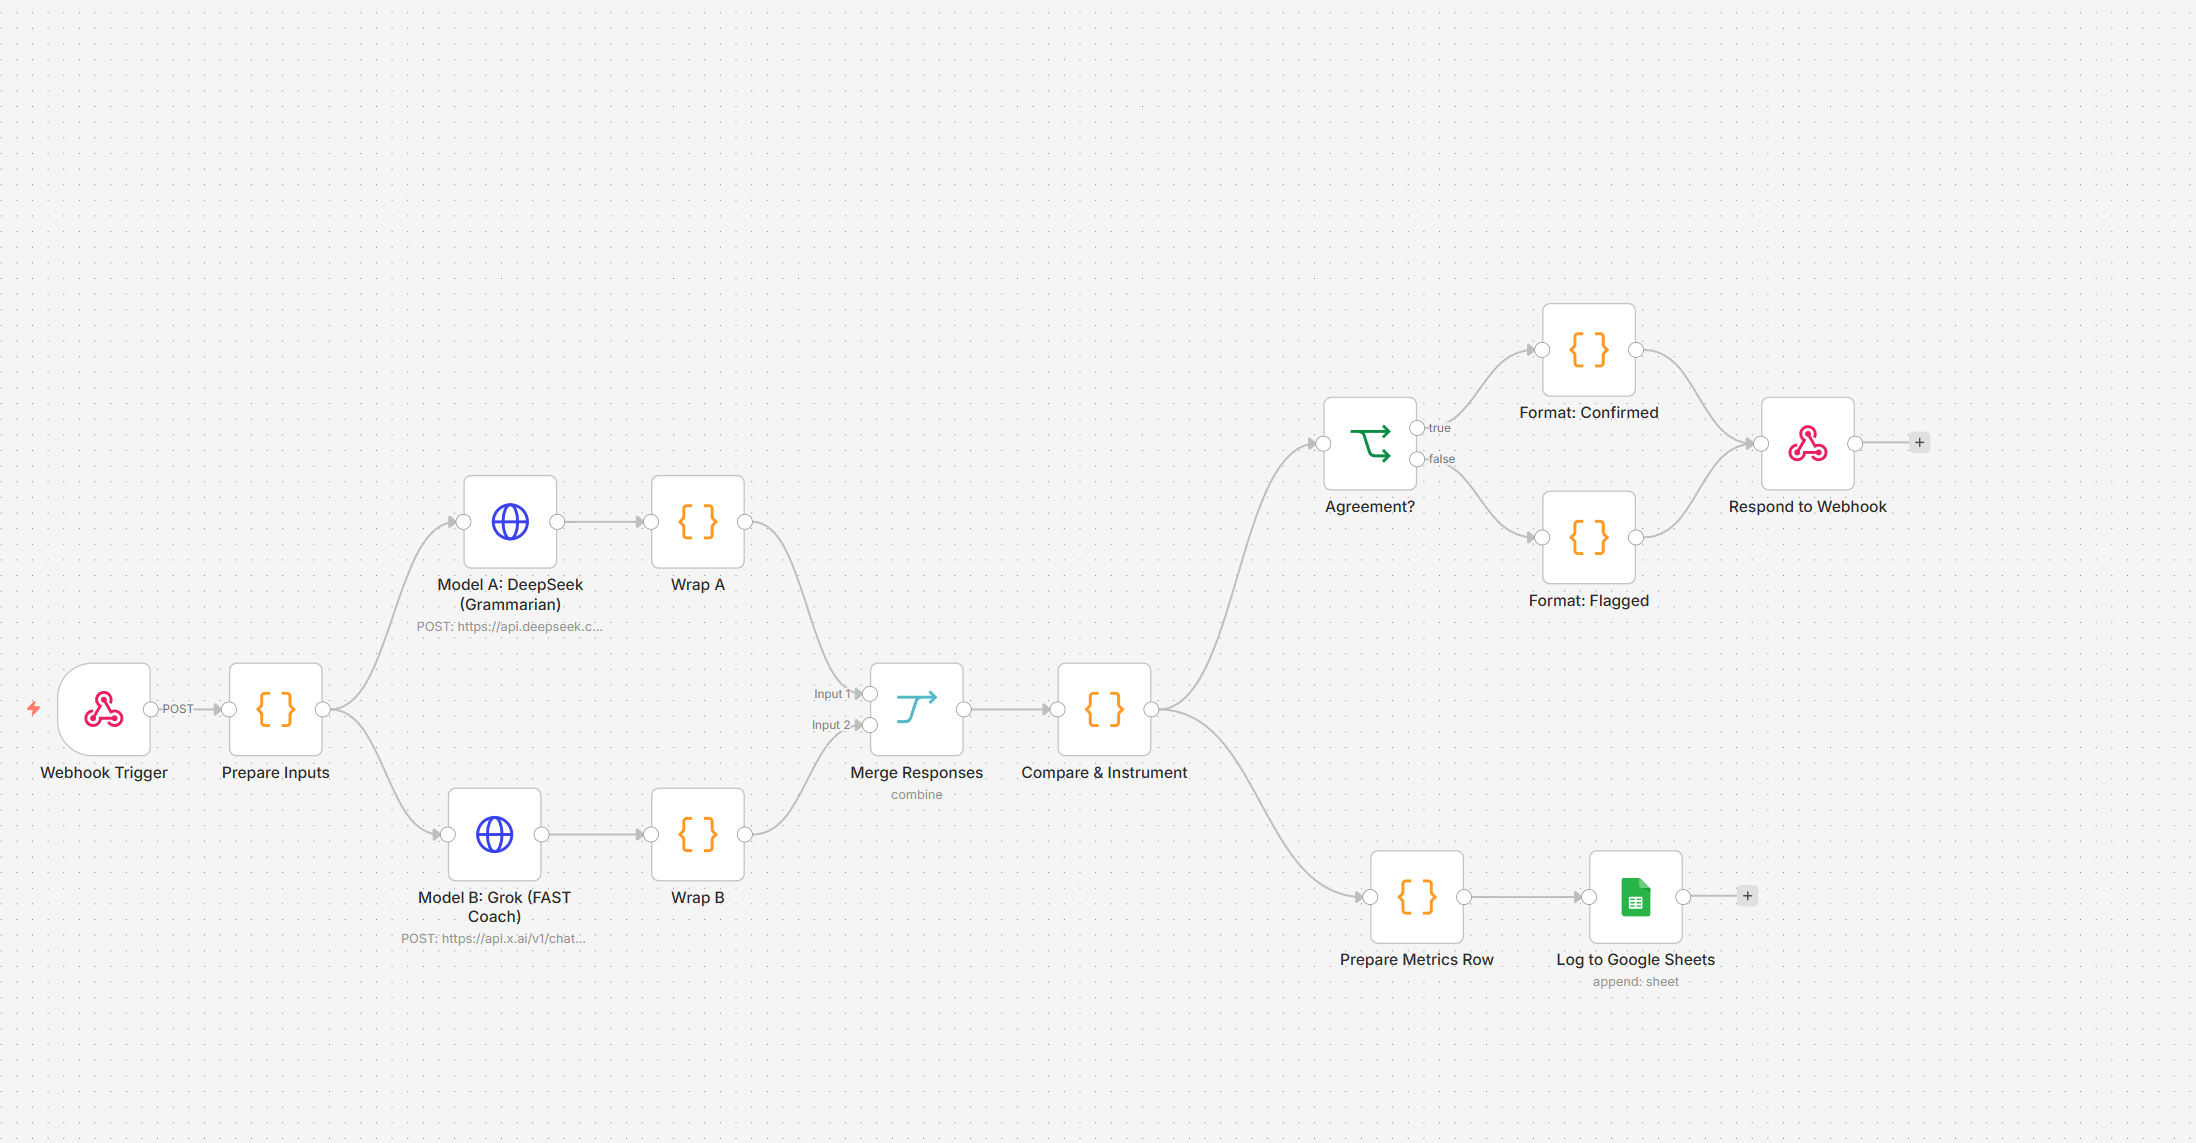
The website app uses an n8n process automation flow. Claude was used to create the workflow based on the described FAST diagram. For diversity the two agents work in parallel from different prompts. The ‘FAST coach’ uses grok-3 and the ‘Grammarian’ uses deepseek-chat. Interactions, Outcomes, and Token Uses are captured in a Google Sheet; over time, this will allow the predicted base rate reliability to be back-checked against that forecast by Claude.